2013年7月12日星期五

choose colors for your plots

1. The HTML 4.01 specification[9] defines sixteen named colors, as follows (names are defined in this context to be case-insensitive):
http://en.wikipedia.org/wiki/Web_colors
CSS 1–2.0 / HTML 3.2–4 / VGA color names
ColorNameHex (RGB)Red
(RGB)
Green
(RGB)
Blue
(RGB)
Hue
(HSL/HSV)
Satur
(HSL)
Light
(HSL)
Satur
(HSV)
Value
(HSV)
CGA number (name); alias
 White#FFFFFF100%100%100%0°0%100%0%100%15 (white)
 Silver#C0C0C075%75%75%0°0%75%0%75%7 (light gray)
 Gray#80808050%50%50%0°0%50%0%50%8 (dark gray)
 Black#0000000%0%0%0°0%0%0%0%0 (black)
 Red#FF0000100%0%0%0°100%50%100%100%12 (high red)
 Maroon#80000050%0%0%0°100%25%100%50%4 (low red)
 Yellow#FFFF00100%100%0%60°100%50%100%100%14 (yellow)
 Olive#80800050%50%0%60°100%25%100%50%6 (brown)
 Lime#00FF000%100%0%120°100%50%100%100%10 (high green); green
 Green#0080000%50%0%120°100%25%100%50%2 (low green)
 Aqua#00FFFF0%100%100%180°100%50%100%100%11 (high cyan); cyan
 Teal#0080800%50%50%180°100%25%100%50%3 (low cyan)
 Blue#0000FF0%0%100%240°100%50%100%100%9 (high blue)
 Navy#0000800%0%50%240°100%25%100%50%1 (low blue)
 Fuchsia#FF00FF100%0%100%300°100%50%100%100%13 (high magenta); magenta
 Purple#80008050%0%50%300°100%25%100%50%5 (low magenta)
2. using colors in R
http://research.stowers-institute.org/efg/Report/UsingColorInR.pdf


interiorfontHTMLbgcolor=Red<GreenBlueColor
Black[Color 1]#000000#000000000[Black]
White[Color 2]#FFFFFF#FFFFFF255255255[White]
Red[Color 3]#FF0000#FF000025500[Red]
Green[Color 4]#00FF00#00FF0002550[Green]
Blue[Color 5]#0000FF#0000FF00255[Blue]
Yellow[Color 6]#FFFF00#FFFF002552550[Yellow]
Magenta[Color 7]#FF00FF#FF00FF2550255[Magenta]
Cyan[Color 8]#00FFFF#00FFFF0255255[Cyan]
[Color 9][Color 9]#800000#80000012800[Color 9]
[Color 10][Color 10]#008000#00800001280[Color 10]
[Color 11][Color 11]#000080#00008000128[Color 11]
[Color 12][Color 12]#808000#8080001281280[Color 12]
[Color 13][Color 13]#800080#8000801280128[Color 13]
[Color 14][Color 14]#008080#0080800128128[Color 14]
[Color 15][Color 15]#C0C0C0#C0C0C0192192192[Color 15]
[Color 16][Color 16]#808080#808080128128128[Color 16]
[Color 17][Color 17]#9999FF#9999FF153153255[Color 17]
[Color 18][Color 18]#993366#99336615351102[Color 18]
[Color 19][Color 19]#FFFFCC#FFFFCC255255204[Color 19]
[Color 20][Color 20]#CCFFFF#CCFFFF204255255[Color 20]
[Color 21][Color 21]#660066#6600661020102[Color 21]
[Color 22][Color 22]#FF8080#FF8080255128128[Color 22]
[Color 23][Color 23]#0066CC#0066CC0102204[Color 23]
[Color 24][Color 24]#CCCCFF#CCCCFF204204255[Color 24]
[Color 25][Color 25]#000080#00008000128[Color 25]
[Color 26][Color 26]#FF00FF#FF00FF2550255[Color 26]
[Color 27][Color 27]#FFFF00#FFFF002552550[Color 27]
[Color 28][Color 28]#00FFFF#00FFFF0255255[Color 28]
[Color 29][Color 29]#800080#8000801280128[Color 29]
[Color 30][Color 30]#800000#80000012800[Color 30]
[Color 31][Color 31]#008080#0080800128128[Color 31]
[Color 32][Color 32]#0000FF#0000FF00255[Color 32]
[Color 33][Color 33]#00CCFF#00CCFF0204255[Color 33]
[Color 34][Color 34]#CCFFFF#CCFFFF204255255[Color 34]
[Color 35][Color 35]#CCFFCC#CCFFCC204255204[Color 35]
[Color 36][Color 36]#FFFF99#FFFF99255255153[Color 36]
[Color 37][Color 37]#99CCFF#99CCFF153204255[Color 37]
[Color 38][Color 38]#FF99CC#FF99CC255153204[Color 38]
[Color 39][Color 39]#CC99FF#CC99FF204153255[Color 39]
[Color 40][Color 40]#FFCC99#FFCC99255204153[Color 40]
[Color 41][Color 41]#3366FF#3366FF51102255[Color 41]
[Color 42][Color 42]#33CCCC#33CCCC51204204[Color 42]
[Color 43][Color 43]#99CC00#99CC001532040[Color 43]
[Color 44][Color 44]#FFCC00#FFCC002552040[Color 44]
[Color 45][Color 45]#FF9900#FF99002551530[Color 45]
[Color 46][Color 46]#FF6600#FF66002551020[Color 46]
[Color 47][Color 47]#666699#666699102102153[Color 47]
[Color 48][Color 48]#969696#969696150150150[Color 48]
[Color 49][Color 49]#003366#003366051102[Color 49]
[Color 50][Color 50]#339966#33996651153102[Color 50]
[Color 51][Color 51]#003300#0033000510[Color 51]
[Color 52][Color 52]#333300#33330051510[Color 52]
[Color 53][Color 53]#993300#993300153510[Color 53]
[Color 54][Color 54]#993366#99336615351102[Color 54]
[Color 55][Color 55]#333399#3333995151153[Color 55]
[Color 56][Color 56]#333333#333333515151[Color 56]
Excel only recognizes names for Color 1 through 8 (Black, White, Red, Green, Blue, Yellow, Magenta, and Cyan).  The colors 1-16 are widely understood color names from the VGA color palette.  Of the 56 colors only 40 colors appear on the palette.  The 40 colors names indicated on the Excel color palette (see below) are for descriptive purposes only. 

2013年7月2日星期二

parsing arguements in a R script

http://ggorjan.blogspot.ca/2013/07/parse-arguments-of-r-script.html?utm_source=feedburner&utm_medium=feed&utm_campaign=Feed:+GregorGorjancsBlog+(Gregor+Gorjanc's+blog)

R can be used also as a scripting tool. We just need to add shebang in the first line of a file (script):

#!/usr/bin/Rscript

and then the R code should follow.

Often we want to pass arguments to such a script, which can be collected in the script by the commandArgs() function. Then we need to parse the arguments and conditional on them do something. I came with a rather general way of parsing these arguments using simply these few lines:
## Collect arguments
args <- a="" href="http://inside-r.org/r-doc/base/commandArgs" style="color: #b81909; text-decoration: none;">commandArgs
(TRUE)   ## Default setting when no arguments passed if(length(args) < 1) { args <- a="" href="http://inside-r.org/r-doc/base/c" style="color: #b81909; text-decoration: none;">c("--help") }   ## Help section if("--help" %in% args) { cat(" The R Script   Arguments: --arg1=someValue - numeric, blah blah --arg2=someValue - character, blah blah --arg3=someValue - logical, blah blah --help - print this text   Example: ./test.R --arg1=1 --arg2="output.txt" --arg3=TRUE \n\n")   q(save="no") }   ## Parse arguments (we expect the form --arg=value) parseArgs <- a="" href="http://inside-r.org/r-doc/base/function" style="color: #b81909; text-decoration: none;">function(x) strsplit(sub("^--", "", x), "=") argsDF <- a="" href="http://inside-r.org/r-doc/base/as.data.frame" style="color: #b81909; text-decoration: none;">as.data.frame(do.call("rbind", parseArgs(args))) argsL <- a="" href="http://inside-r.org/r-doc/base/as.list" style="color: #b81909; text-decoration: none;">as.list(as.character(argsDF$V2)) names(argsL) <- argsdf="" nbsp="" span="" style="font-style: italic;">## Arg1 default if(is.null(args$arg1)) { ## do something }   ## Arg2 default if(is.null(args$arg2)) { ## do something }   ## Arg3 default if(is.null(args$arg3)) { ## do something }
 
## ... your code here ...
Created by Pretty R at inside-R.org

It is some work, but I find it pretty neat and use it for quite a while now. I do wonder what others have come up for this task. I hope I did not miss some very general solution.

2013年6月27日星期四

distinguish effects of geographic and ecological isolation on differentiation

Populations can be genetically isolated by both geographic distance and by differences in their ecology or environment that decrease the rate of successful migration. Empirical studies often seek to investigate the relationship between genetic differentiation and some ecological variable(s) while accounting for geographic distance, but common approaches to this problem (such as the partial Mantel test) have a number of drawbacks. In this article, we present a Bayesian method that enables users to quantify the relative contributions of geographic distance and ecological distance to genetic differentiation between sampled populations or individuals. We model the allele frequencies in a set of populations at a set of unlinked loci as spatially correlated Gaussian processes, in which the covariance structure is a decreasing function of both geographic and ecological distance. Parameters of the model are estimated using a Markov chain Monte Carlo algorithm. We call this method Bayesian Estimation of Differentiation in Alleles by Spatial Structure and Local Ecology (BEDASSLE), and have implemented it in a user-friendly format in the statistical platform R. We demonstrate its utility with a simulation study and empirical applications to human and teosinte datasets.

http://arxiv.org/abs/1302.3274

Piping with samtools, bwa and bedtools

http://www.biostars.org/p/43677/

In this tutorial I will introduce some concepts related to unix piping. Piping is a very useful feature to avoid creation of intermediate use once files. It is assumed that bedtools, samtools, and bwa are installed.
Lets begin with a typical command to do paired end mapping with bwa: (./ means look in current directory only)
#-t 4 is for using 4 threads/cores
bwa aln -t 4 ./hg19.fasta ./s1_1.fastq > ./s1_1.sai
bwa aln -t 4 ./hg19.fasta ./s1_2.fastq > ./s1_2.sai
bwa sampe ./hg19.fasta ./s1_1.sai ./s1_2.sai ./s1_1.fastq ./s1_2.fastq > s1.sam
Supposed we wish to compress sam to bam, sort, remove duplicates, and create a bed file.
samtools view -Shu s1.sam > s1.bam
samtools sort s1.bam s1_sorted
samtools rmdup -s s1_sorted.bam s1_sorted_nodup.bam
bamToBed -i s1_sorted_nodup.bam > s1_sorted_nodup.bed
This workflow above creates many files that are only used once (such as s1.bam) and we can use the unix pipe utility to reduce the number intermediate files created. The pipe function is the character | and what it does is take the output from one command and sets it as input for next command (assuming next command knows how to deal with this input).
For example, when you type in head myfile.txt the command 'head' will read first 10 lines of myfile.txt and output it (by default) to the display (stdout) so you will see the first 10 lines printed on your screen. However, if you were to do something like this:
head myfile.txt | wc -l
you will instead get 10 printed out on your screen. What the pipe command did was take the output of head command and used it as input for the wordcount (wc) command. wc -l command will count the number of lines passed in (which is 10 since head by default prints the first 10 lines). An equivalent command would be
head myfile.txt > myfile_top10_lines.txt
wc -l myfile_top10_lines.txt
By using the pipe command we are able to eliminate the intermediate file that was generated (myfile_top10_lines.txt).
Below is an example of how pipe command can be used in samtools
bwa aln -t 4 ./hg19.fasta ./s1_1.fastq > ./s1_1.sai
bwa aln -t 4 ./hg19.fasta ./s1_2.fastq > ./s1_2.sai
bwa sampe ./hg19.fasta ./s1_1.sai ./s1_2.sai ./s1_1.fastq ./s1_2.fastq | \
samtools view -Shu - | \
samtools sort - - | \
samtools rmdup -s - - | \
tee s1_sorted_nodup.bam | \
bamToBed > s1_sorted_nodup.bed
A couple of things I wanted to point out here:
  • The \ symbol after the pipe symbol tells the terminal that I want to keep writing command on the next line, that way you can have multiline commands instead of super-long command on one line.
  • The tee command takes the information being piped and creates a file while passing the data along the pipe, this command is useful if you want to save an intermediate file but still need to do additional processing. (Think of a T shaped drain pipe)
  • The - symbol in samtools it to tell the samtools program to take the input from pipe
  • It is not recommended you run this command all at once like I showed above if you have a giant bam file because sort will take forever. Running things in a pipe can be more space efficient since you are not storing intermediate files but can create issues/bottlenecks elsewhere. If problems arise, run the pieces without piping to troubleshoot.
  • The two bwa aln commands can be run in parallel (for example: on another machine) before the sampe command
Other common uses of pipes that I have not shown above it to pipe output into snp calling, you can find some examples here: (NOTE: pileupcommand is depreciated, the new way to call SNPs using samtools using mpileup command)
samtools merge - *.bam | tee merged.bam | samtools rmdup - - | tee rmdup.bam | samtools mpileup - uf ./hg19.fasta - | bcftools view -bvcg - | gzip > var.raw.bcf.gz
Compressing files with gzip can save a lot of space, but makes these files non-human readable (if you use the head or less command it will give you gibberish). To view these files you can use zless and zcat command.
zless var.raw.bcf.gz #similar to gzip -cd var.raw.bcf.gz | less
zcat var.raw.bcf.gz | head
In case you are wondering if there is a way to run bwa sampe without storing intermediate sai files the command below will do this:
bwa sampe ./hg19.fasta <(bwa aln -t 4 ./hg19.fasta ./s1_1.fastq) <(bwa aln -t 4 ./hg19.fasta ./s1_2.fastq) ./s1_1.fastq ./s1_2.fastq | samtools view -Shb /dev/stdin > s1.bam
Notice here that I used the -b command instead of -u command in samtools view. -u is useful for piping since it spits out an uncompressed bam so you don't have to waste CPU cycles compressing/decompressing at every step, however, if you have a file you want to store, it would be better to compress it with -b. Additionally, I used /dev/stdin instead of using the - symbol, they both mean the same thing (afaik) and I wanted to point it out that /dev/stdin might be a more explicit way of showing things. (ie samtools view -Shu /dev/stdin )

The Elements of Bioinformatics

http://elements.eaglegenomics.com/

2013年6月16日星期日

X11 forwarding over SSH: run remote graphical app and display locally

http://linuxcommando.blogspot.ca/2013/05/x11-forwarding-over-ssh-run-remote.html

In the modern networked environment, we often wish to run an application on a remote host while we are comfortably logged in on our local computer.
Assuming both machines are Linux-based, and the application runs on the graphical X desktop, the following approaches come to mind:
  • VNC
  • X11 forwarding over SSH
This article focuses only on X11 forwarding. X11 forwarding over SSH enables you to run a remote X app and display it locally, with traffic between the 2 hosts encrypted by SSH.
For X11 forwarding over SSH to work, both the SSH client and SSH server must be properly configured.
X11 forwarding must be enabled on The SSH server side. This is the machine where the application resides. To enable the feature, make sure the X11 configuration file /etc/ssh/sshd_config on the server contains this line:
X11Forwarding yes
If you edit the said file, you need to restart the sshd daemon for the change to take effect.
On Debian or Ubuntu systems, you restart the SSH daemon like this:
$ sudo service ssh restart
[ ok ] Restarting OpenBSD Secure Shell server: sshd.
$
On the ssh client side, you need to run SSH command with the proper parameters. For instance, suppose you want to run the xclockapplication on the remote SSH server and have it displayed back on the local client.
$ ssh -fX peter@192.168.1.112 xclock 
peter@192.168.1.112's password: 
$
The -X parameter allows an one-off X11 forwarding session.
The -f parameter instructs the SSH client to go to the background just before xclock is run.
If you want to permanently enable X11 forwarding for an user, insert this line in the user's own ~/.ssh/config file on the local host.
ForwardX11 yes 
With X11 forwarding permanently enabled for the client, you can leave out the -X parameter:
$ ssh -f peter@192.168.1.112 xclock 
peter@192.168.1.112's password: 
$
If X11 forwarding is not enabled on the SSH server, any attempt to tunnel X11 will fail with the following error message:
$ ssh -X peter@192.168.1.112 xclock 
peter@192.168.1.112's password: 
X11 forwarding request failed on channel 0
Error: Can't open display: 
$
If X11 forwarding is properly enabled on the server side, you will see a nice looking clock displayed on your local screen.

2013年5月26日星期日

Framework for evaluating variant detection methods: comparison of aligners and callers

I’ll show a 12 way comparison between 2 different aligners (novoalign and bwa mem), 2 different post-alignment preparation methods (GATK best practices and the Marth lab’s gkno pipeline), and 3 different variant callers (GATK UnifiedGenotyper, GATK HaplotypeCaller, and FreeBayes). This allows comparison of openly available methods (bwa mem, gkno preparation, and FreeBayes) with those that require licensing (novoalign, GATK’s variant callers). I’ll also describe bcbio-nextgen, the fully automated open-source pipeline used for variant calling and evaluation, which allows others to easily bring this methodology into their own work and extend this analysis.

2013年5月25日星期六

How does your bash prompt look like

http://kevin-gattaca.blogspot.ca/

http://www.cyberciti.biz/tips/howto-linux-unix-bash-shell-setup-prompt.html

http://www.maketecheasier.com/8-useful-and-interesting-bash-prompts/2009/09/04


2013年5月18日星期六

Multiple populations of artemisinin-resistant Plasmodium falciparum in Cambodia

http://www.nature.com/ng/journal/vaop/ncurrent/full/ng.2624.html

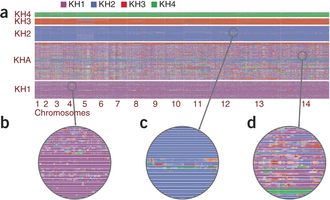
We describe an analysis of genome variation in 825 P. falciparum samples from Asia and Africa that identifies an unusual pattern of parasite population structure at the epicenter of artemisinin resistance in western Cambodia. Within this relatively small geographic area, we have discovered several distinct but apparently sympatric parasite subpopulations with extremely high levels of genetic differentiation. Of particular interest are three subpopulations, all associated with clinical resistance to artemisinin, which have skewed allele frequency spectra and high levels of haplotype homozygosity, indicative of founder effects and recent population expansion. We provide a catalog of SNPs that show high levels of differentiation in the artemisinin-resistant subpopulations, including codon variants in transporter proteins and DNA mismatch repair proteins. These data provide a population-level genetic framework for investigating the biological origins of artemisinin resistance and for defining molecular markers to assist in its elimination.


2013年4月30日星期二

Cases of Population structure using fineSTRUCTURE

1.
http://eurogenes.blogspot.ca/2012/01/eurogenes-north-euro-clusters-phase-2.html

2.
http://www.harappadna.org/category/chromopainter-2/

3.
http://blogs.discovermagazine.com/gnxp/2012/01/population-structure-using-haplotype-data/#.UYAD1HE-sRN

Rscript example - using R to executable functions


I use Rscript as my prime scripting language to perform some command-line tasks. The reason for this is I don’t know much about bash scripts nor perl language. Writing a script in R is very simple if you know R language. But there are a few things need to consider.
  • How to pass arguments to the script
  • Which version of Rscript should you use
  • A facility to provide a bash-line help
I did a simple try and here is an example Rscript how it works

Stamen maps with spplot


Stamen maps with spplot

Several R packages provide an interface to query map services (Google Maps,Stamen Maps or OpenStreetMap) to obtain raster images from them. As far as I know, there are three packages devoted to this task: RgoogleMaps,OpenStreetMap and ggmap. The latter two are increasingly popular with a wide collection of providers.

2013年4月26日星期五

yandell lab - on human population genetics

http://www.yandell-lab.org/software/index.html


 VAAST

VAAST (the Variant Annotation, Analysis & Search Tool) is a probabilistic search tool for identifying damaged genes and their disease-causing variants in personal genome sequences. VAAST builds upon existing amino acid substitution (AAS) and aggregative approaches to variant prioritization, combining elements of both into a single unified likelihood-framework that allows users to identify damaged genes and deleterious variants with greater accuracy, and in an easy-to-use fashion. VAAST can score both coding and non-coding variants, evaluating the cumulative impact of both types of variants simultaneously. VAAST can identify rare variants causing rare genetic diseases, and it can also use both rare and common variants to identify genes responsible for common diseases. VAAST thus has a much greater scope of use than any existing methodology.

 MAKER 2 (updated 07-22-2012)

MAKER is a portable and easily configurable genome annotation pipeline. It's purpose is to allow smaller eukaryotic and prokaryotic genomeprojects to independently annotate their genomes and to create genome databases. MAKER identifies repeats, aligns ESTs and proteins to a genome, produces ab-initio gene predictions and automatically synthesizes these data into gene annotations having evidence-based quality values. MAKER is also easily trainable: outputs of preliminary runs can be used to automatically retrain its gene prediction algorithm, producing higher quality gene-models on seusequent runs. MAKER's inputs are minimal and its ouputs can be directly loaded into a GMOD database. They can also be viewed in the Apollo genome browser; this feature of MAKER provides an easy means to annotate, view and edit individual contigs and BACs without the overhead of a database. MAKER should prove especially useful for emerging model organism projects with minimal bioinformatics expertise and computer resources.

 RepeatRunner

RepeatRunner is a CGL-based program that integrates RepeatMasker with BLASTX to provide a comprehensive means of identifying repetitive elements. Because RepeatMasker identifies repeats by means of similarity to a nucleotide library of known repeats, it often fails to identify highly divergent repeats and divergent portions of repeats, especially near repeat edges. To remedy this problem, RepeatRunner uses BLASTX to search a database of repeat encoded proteins (reverse transcriptases, gag, env, etc...). Because protein homologies can be detected across larger phylogenetic distances than nucleotide similarities, this BLASTX search allows RepeatRunner to identify divergent protein coding portions of retro-elements and retro-viruses not detected by RepeatMasker. RepeatRunner merges its BLASTX and RepeatMasker results to produce a single, comprehensive XML-based output. It also masks the input sequence appropriately. In practice RepeatRunner has been shown to greatly improve the efficacy of repeat identifcation. RepeatRunner can also be used in conjunction with PILER-DF - a program designed to identify novel repeats - and RepeatMasker to produce a comprehensive system for repeat identification, characterization, and masking in the newly sequenced genomes.

ImagePlane

ImagePlane is python based image analysis software designed for the automated analysis of images of the animal S. mediterranea. This software allows the animals's neoblasts to be quantified and tested for assymetries along its veritcal and hoizontal axes. ImagePlane also allows simple mophology categorizations to be made based on the overall shape of the animal.

 CGL

CGL is a software library designed to facilitate the use of genome annotations as substrates for computation and experimentation; we call it "CGL", an acronym for Comparitive Genomics Library, and pronounce it "Seagull". The purpose of CGL is to provide an informatics infrastructure for a laboratory, department, or research institute engaged in the large-scale analysis of genomes and their annotations.

2013年4月25日星期四

GateOne - a web-based Terminal Emulator and SSH client

http://liftoffsoftware.com/Products/GateOne

a web-based Terminal Emulator and SSH client that brings the power of the command line to the web. It requires no browser plugins and is built on top of a powerful plugin system that allows every aspect of its appearance and functionality to be customized.

duplicate/repeat a character times in terminal


# generate many times of "S"
for i in $(seq 303738); do echo -n 'S'; done; printf "\n" > multi_S

transpose a matrix (from columns to row)


# transpose a matrix (from columns to row)
awk '{for (i=1; i<=NF; i++) a[i]=a[i](NR!=1?FS:"")$i} END {for (i=1; i in a; i++) print a[i]}' file

insert contents of a file to another file at specific line


# insert content of "mao" to file "head", after the line with "source"
sed '/source/r mao' head | less -S

2013年4月24日星期三

DNAPlotter: circular and linear interactive genome visualization

http://bioinformatics.oxfordjournals.org/content/25/1/119.full


Circular and linear DNA diagrams provide a powerful tool for illustrating the features of a genome in their full genomic context. CGView (Stothard and Wishart,2005) is a circular genome viewer that produces PNG, JPEG or scalable vector graphics (SVG) format. It is primarily designed to be part of a pipeline and not an interactive and editable viewer. GenomeDiagram (Pritchard et al., 2006) is a Python module, which can also be used to generate diagrams. GenomePlot (Gibson and Smith, 2003), GenoMap (Sato and Ehira, 2003) and Microbial Genome Viewer (MGV; Kerkhoven et al., 2004), are GUI based but do not provide the ability to directly read in files in the common sequence formats or a filtering tool to define tracks.
Circos (http://mkweb.bcgsc.ca/circos/) is web-based genome comparison visualizer that is configured from flat files. It can be configured for comparisons within a genome or between multiple genomes. There are also commercial packages available that draw circular and linear plots.
Below we present DNAPlotter, a collaborative project combining graphics from the Jemboss (http://emboss.sf.net/Jemboss/) DNA viewer and Artemis (http://www.sanger.ac.uk/Software/Artemis/) libraries to read files and filter features, which has been designed to be a graphical means of customizing circular and linear diagrams.


2013年4月23日星期二

Neurospora crassa - model organism of fungi

N. crassa is used as a model organism.


Crossing the species barrier: genomic hotspots of introgression between two highly divergent Ciona intestinalis species

http://mbe.oxfordjournals.org/content/early/2013/04/05/molbev.mst066.full.pdf+html


ABC running with sliding-windows
Inferring a realistic demographic model from genetic data is an important challenge to gain insights into the historical events during the speciation process and to detect molecular signatures of selection along genomes. Recent advances in divergence population genetics have reported that speciation in face of gene flow occurred more frequently than theoretically expected, but the approaches used did not account for genome wide heterogeneity (GWH) in introgression rates. Here we investigate the impact of GWH on the inference of divergence with gene flow between two cryptic species of the marine modelCiona intestinalis by analysing polymorphism and divergence patterns in 852 protein-coding sequence loci.
These morphologically similar entities are highly diverged molecular-wise, but evidence of hybridisation has been reported in both laboratory and field studies. We compare various speciation models and test for GWH under the ABC framework. Our results demonstrate the presence of significant extents of gene flow resulting from a recent secondary contact after >3 My of divergence in isolation. The inferred rates of introgression are relatively low, highly variable across loci and mostly unidirectional, which is consistent with the idea that numerous genetic incompatibilities have accumulated over time throughout the genomes of these highly-diverged species. A genomic map of the level of gene flow identified two hotspots of introgression, i.e. large genome regions of unidirectional introgression. This study clarifies the history and degree of isolation of two cryptic and partially sympatric model species, and provides a methodological framework to investigate GWH at various stages of speciation process.

CodonPhyML: Fast Maximum Likelihood Phylogeny Estimation under Codon Substitution Models

http://mbe.oxfordjournals.org/content/early/2013/04/02/molbev.mst034.abstract

Markov models of codon substitution naturally incorporate the structure of the genetic code and the selection intensity at the protein level, providing a more realistic representation of protein-coding sequences compared with nucleotide or amino acid models. Thus, for protein-coding genes, phylogenetic inference is expected to be more accurate under codon models. So far, phylogeny reconstruction under codon models has been elusive due to computational difficulties of dealing with high dimension matrices. Here, we present a fast maximum likelihood (ML) package for phylogenetic inference, CodonPhyML offering hundreds of different codon models, the largest variety to date, for phylogeny inference by ML. CodonPhyML is tested on simulated and real data and is shown to offer excellent speed and convergence properties. In addition, CodonPhyML includes most recent fast methods for estimating phylogenetic branch supports and provides an integral framework for models selection, including amino acid and DNA models.

Species distribution models in R

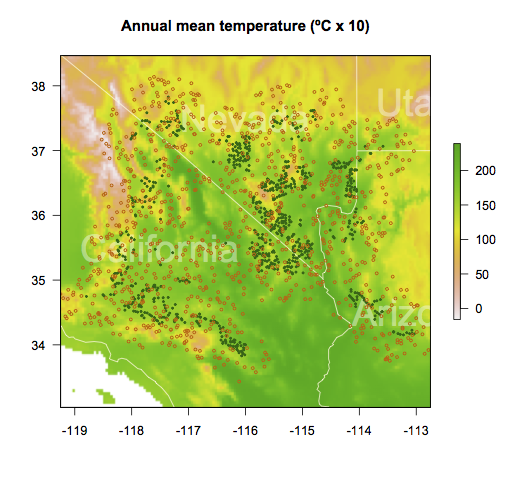
http://www.molecularecologist.com/2013/04/species-distribution-models-in-r/#more-3017


2013年4月22日星期一

Interspecific Divergence of Transcription Networks along Lines of Genetic Variance in Drosophila: Dimensionality, Evolvability and Constraint


Interspecific Divergence of Transcription Networks along Lines of Genetic Variance inDrosophila: Dimensionality, Evolvability and Constraint


Change in gene expression is a major facilitator of phenotypic evolution. Understanding the evolutionary potential of gene expression requires taking into account complex systems of regulatory networks, the structure of which could potentially bias evolutionary trajectories. We analyzed the evolutionary potential and divergence of multigene expression in three well-characterized signaling pathways in Drosophila, the mitogen-activated protein kinase (MapK), the Toll, and the insulin receptor/Foxo (InR/Foxo or InR/TOR) pathways in a multivariate quantitative genetic framework. Gene expression data from a natural population of D. melanogaster were used to estimate the genetic variance–covariance matrices (G) for each network. Although most genes within each pathway exhibited significant genetic variance, the number of independent dimensions of multivariate genetic variance was fewer than the number of genes analyzed. However, for expression, the reduction in dimensionality was not as large as seen for other trait types such as morphology. We then tested whether gene expression divergence between D. melanogaster and an additional six species of the Drosophila genus was biased along the major axes of standing variation observed in D. melanogaster. In many cases, divergence was restricted to directions of phenotypic space harboring above average levels of genetic variance in D. melanogaster, indicating that genetic covariances between genes within pathways have biased interspecific divergence. We tested whether co-expression of genes in both sexes has also biased the pattern of divergence. Including cross-sex genetic covariances increased the degree to which divergence was biased along major axes of genetic variance, suggesting that the co-expression of genes in males and females can generate further constraints on divergence across the Drosophila phylogeny. In contrast to patterns seen for morphological traits in vertebrates, transcriptional constraints do not appear to break down as divergence time between species increases, instead they persist over tens of millions of years of divergence.

2013年4月21日星期日

OpenStreetMap package of R - get beautiful maps


The bigest change in the new version is the addition of dozens of tile servers, giving the user the option of many different map looks, including those from Bing, MapQuest and Apple.
nm = c("osm", "maptoolkit-topo",
"waze", "mapquest", "mapquest-aerial",
"bing", "stamen-toner", "stamen-terrain",
"stamen-watercolor", "osm-german", "osm-wanderreitkarte",
"mapbox", "esri", "esri-topo",
"nps", "apple-iphoto", "skobbler",
 "opencyclemap", "osm-transport",
"osm-public-transport", "osm-bbike", "osm-bbike-german")

png(width=1200,height=2200)
par(mfrow=c(6,4))
for(i in 1:length(nm)){
 print(nm[i])
 map = openmap(c(lat= 38.05025395161289,   lon= -123.03314208984375),
   c(lat= 36.36822190085111,   lon= -120.69580078125),
   minNumTiles=9,type=nm[i])
 plot(map)
 title(nm[i],cex.main=4)
}
dev.off()


http://blog.fellstat.com/?p=356

a Little Book of R for Bioinformatics

http://a-little-book-of-r-for-bioinformatics.readthedocs.org/en/latest/#


R 3.0.0 - a new R edition

1.
http://nsaunders.wordpress.com/2013/04/04/a-brief-note-r-3-0-0-and-bioinformatics/

2. install R, in windows and linux and new features of this new R
http://www.r-statistics.com/

2013年4月17日星期三

A wide extent of inter-strain diversity in virulent and vaccine strains of alpha-herpesviruses

Good example on de novo genome assembly, annotation, comparsion

http://genomics-pubs.princeton.edu/prv/scripts.shtml


Overview & Table of Contents

Part I - Pre-Assembly Processing

These steps take raw Illumina® sequence data and prepare it for de novo assembly, using a series of quality-controls and filters.

Part II - De novo Assembly & Genome Finishing

This phase of genome production takes high-quality short sequence reads, and by homology-based overlaps, joins them into longer and longer pieces.

Part III - Quality Assessment of New Genomes

These steps assess the quality of the assembly and address any inconsistencies. These scripts function in conjunction with wet-bench analyses, such as restriction fragment length polymorphism (RFLP) analysis and directed PCR validations.

Part IV - Annotation & Genome Comparison

This phase involves annotation, curation, and comparison of multiple genome sequences to reveal interesting biological features.

Addendum - Relevant Websites and Lists of Scripts Used

All scripts used are freely available online (web links provided) or are available here (see Downloads link on left) for download and free use.